
hlfshell Keith Chester
Maker. Roboticist. Person.
Keith Chester
My current startup

written by a human for other humans


sandboxed

sandboxed logo

The most common theme in most of my golang libraries is - “I needed it for another larger project”. Queue a side quest and boom, new library. sandboxed is no different.

sandboxed is a Go virtual filesystem for storing untrusted data as encrypted chunks. The original project driving the need for this is still too early; I’ll talk more about it when I have something substantial to share. I wanted the ability to download arbitrary binary data and protect the system from it.

This might make a few of you go “why the hell would you want to do that?”; well, wait for the other project. Others might point out that a virtual machine would be a great way to isolate the payload. No argument here. I have my reasons for wanting to avoid virtualization here.

So what does sandboxed do? It presents an fs interface for use in golang where a manifest file tracks individual files within the “file system”. Every file is streamed through a per file encryption buffer when writing data to disk. The encryption is less about security of data exfiltration and more about unpredictable scrambling of potentially malicious payloads.

You are still susceptible to malicious payloads at time of reading (or, and please don’t do this, execution) but that can be handled with care towards what you’re handling at any point.

sandboxed is mostly about protecting the host system from at-rest data triggering exploits from scanning / read attacks.
I am unreasonably excited about Taalas

I find myself unreasonably excited for the work that Taalas is doing. They’re turning open weight models directly into ASICs (application specific integrated circuits) so that the chip essentially acts as the model - and only as the model. You get raw transistor switching speed within the model. Not only does this result in incredibly fast computation (~15k tokens a second for llama 8b!) but you are doing so at ridiculously low power consumption and efficiency.

I’ve heard some rumors that are tempting and I hope are true. First - a Qwen 27B model is in the works; this is a great model that can do a lot of the simpler tasks you’d want from local AI, and can even do a bit of coding well. Importantly it’s a very strong tool calling agent, so it could very easily hand off tasks to additional AIs when needing capable compute. Supposedly cost to produce the board is ~$400 (again - unstantiated rumors here) which would mean an attractive $800 price tag.

If we start to look at large models - 70b and 120b open models - being translated to this style of chip, we could be looking at an explosion of local AI that completely changes the costs (both monetary and power consumption) of AI application. But…

I truly don’t expect that they will ever make it to selling consumer boards; I fully expect them to either find themselves gobbled up by NVIDIA to secure potential competition, or for someone like Google/Samsung/Apple to buy them to build out the equivalent for phones.

Firecracker + poprocks (DEVx)

I just gave a talk at DEVx giving a very early alpha preview of poprocks, a module providing simple golang primitives for building and working with Firecracker microvms. While it can be used serverside, I talk about utilizing it instead as a client side solution for isolated, malicious actor “safe” execution environments - especially for AI agents.

What comes after the token discount bubble pops?

Coding agents are amazing - sure. I’m a fan and heavy user of them too, especially CLI agents. BUT - the existing coding subscriptions heavily discount token usage, to the point that most users are unaware of just how many tokens they are actually burning at any given moment to run their agents. This blissful ignorance is perfectly fine as long as the discounsts continue; the pain of running the agents aren’t being felt by the end user.

Why are they so heavily discounted? There’s a race to secure funding and users by the big AI model providers, resulting in heavily (prohibitively and unsustainably) discounted tokens to try and build a user base with dependence on them as a provider. Either users will have no choice but to deal with price hikes, or one of these providers will be the “last man standing” and finally make good on their untenable investor promises.

When the AI economic bubble pops for these providers (which, barring any major discovery in terms of hardware / model architecture, will happen), we’re likely going to see a large increase in token pricing. The next step? I see three possible outcomes.

1 - Tooling favors mixed model approaches, where specially tuned agents appropriately route to different model sizes of varying costs based on user preferences for costs and task categorization. We don’t need Claude Opus to center a div, but we do need it for a very complex architectural change. It wouldn’t surprise me that, for internal cost saving, this approach is implemented by the providers themselves as a singular packaged model endpoint or incorporated into the tooling.

2 - We see a sharp rise of business-focused large scale token pricing packages, similar to how we see reserved instance pricing in cloud infrastructure. Buying a years worth of tokens up front based on projected dev usage nets businesses discounts. This doesn’t bode great for model providers though - it creates a larger scale race to the bottom.

3 - Developers and product builders start buying the best possible pro-sumer hardware for headless agent machines (current day equivalent at time of posting would be something like an AMD Strix Halo Processor, like the Framework Desktop (which can run heavily quantized 70B models) ) to run smaller models that can do MOST work, but can call out or pass over to a more expensive model as need be. A kind of local model play on # 1.

I’m personally hoping for some mixture of 3 and 2. I would love to be able to run models locally, but understand that the hardware scale is a long way out from becoming cheaper or consumer grade. Being able to reserve token pricing in bulk to hand off on “capable enough” models to occasionally “upscale” is likely key.

Plus I just prefer local, user owned compute.

ARC-AGI-3 beta is live!

ARC-AGI-3 beta is live!

For the past few months I’ve been working for the ARC Prize - a non profit organization built around the idea of an Abstract and Reasoning Corpus - a set of reasoning games that are easy for humans to quickly and efficiently figure out, play, and solve - but near impossible for even the most cutting edge models. [Paper]

…and today we officially launched the beta of our toolkit and three games for the public to try out!

For ARC-AGI-3, we’ve prepped over 150 games to test AI. I’ve been building out tooling (most notably the benchmarking agent tools) to make it dead simple to test and research models and various agentic architectures.

Using this tooling (and I have more to release soon!) I’ve also been researching how models reason about these games. I’m trying to develop new architectures and techniques to maximize performance of the models and zero in on how these models reason internally and understand uniquely abstract state spaces. This is acutally quite difficult; these games are deceptively simple - outright easy for humans - but even so-called-superhuman LLMs and AI products can’t solve a single one of them.

Check it out and feel free to reach out to me to chat about it.

threadsafe_datastore

Just released threadsafe_datastore, a simple, convenient thread-safe data store for Python.

I kept rebuilding this feature to pass around context within AI agents working on the same data across multiple threads. I kept wanting a simple atomic datastore that was convenient to work with. I originally built it for arkaine | git |. So - here it is as a stand alone package for easier use. I also improved context management for real easy multi-step operations in case you need to do something real custom.

from threadsafe_datastore import Datastore

store = Datastore()
store["counter"] = 0
store.increment("counter", 5)  # Returns 5

# Nested dictionary support
store["nested"] = {"items": []}
store.append(["nested", "items"], "value1")

# Thread safe multi-step w/ context management:
with store as unlocked:
    unlocked["a"] = 1

    # This would be unsafe without the context:
    unlocked["b"] = unlocked.get("a", 0) + 1

Give it a try: pip install threadsafe-datastore

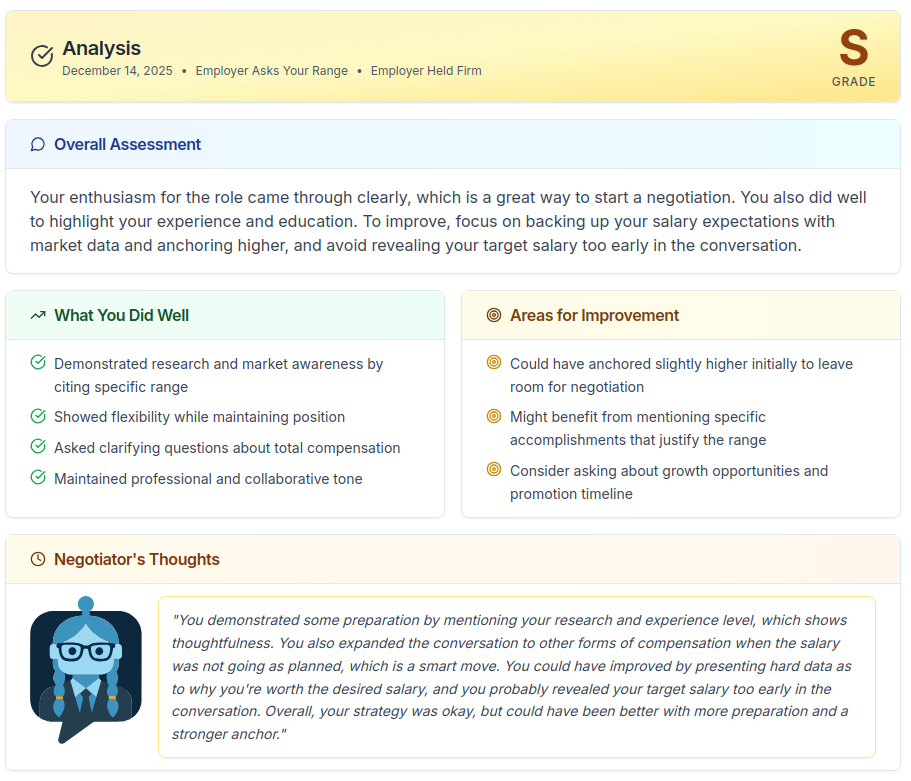
Salary Negotiation Live on HiredCoach

Salary Negotiation Live on HiredCoach — selected image
Salary Negotiation Live on HiredCoach — thumbnail Salary Negotiation Live on HiredCoach — thumbnail

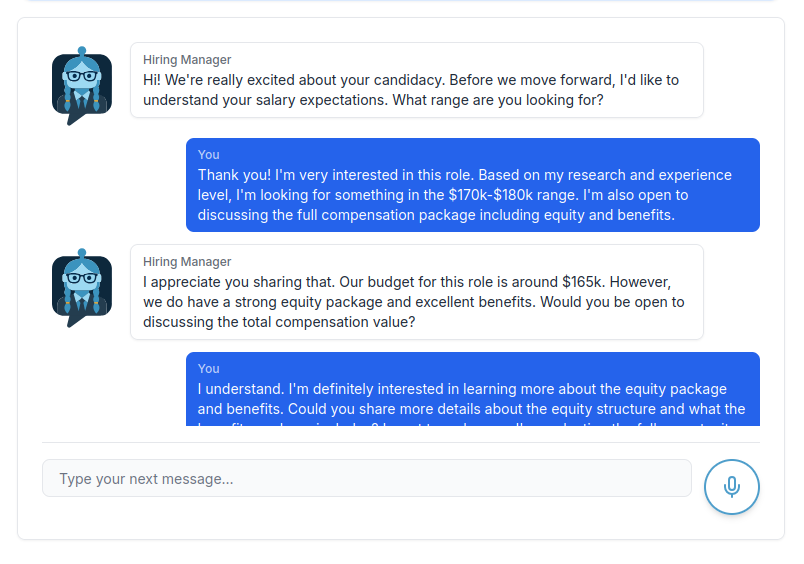
Right off the bat I had users asking for salary negotiation as a feature on HiredCoach. Apparently I’m not the only one that dreads the process of asking for more money and the tension the conversation can have.

It’s live now. I went from idea to prototype in about a day, and only a few more days for the feature to be 99% there. I definitely can think of a few things I’d like to improve on it but I want it in the hands of users first.

Updated SafeStop

About five years ago (ok, that hurt to type. The days are long but the years are short…) I wrote SafeStop. I had made it to coordinate proper shutdown protocols across multiple services running in a large monolith application.

I decided to renew it, modernize it, and added some dependency features (so service B can shutdown after service A is shutdown, etc).

Another product of my recent golang kick.

structured-parse release

Just released structured-parse, a multi-language parser for block labeled LLM output. It’s based on the parser I had built for arkaine.

Here’s what I mean by “block labeleled” output:

Thought: I need to search for information about robots
Action: search
Action Input: {"query": "robots and why they're so cool", "max_results": 5}

This output is not only more human readable, but also easier for LLMs to produce. But there’s a catch - LLMs tend to still introduce nondeterministic volatility towards these outputs; humans are just good about reading through that. structured-parse is a robust parser that can deal with this, allowing LLMs to reliably follow instructions and allowing your code to parse it into clean, typed data structures.

structured-parse is written in Go with exports to TypeScript/JavaScript and Python via WebAssembly; so it’s all golang at its core.

Give it a try!

docker-harness got a mini-makeover

Just pushed a pretty significant update to docker-harness. It was a tool I created originally to power some of my Docker containerized database tests.

I pulled out the dependencies for each database to modularize it a bit. Each database module (MySQL, PostgreSQL, Redis, Memcached) now has its own go.mod and go.sum, which means you only pull in the dependencies for the databases you actually need.

Also added some dependency updates, taking out old dependencies that weren’t needed anymore, while also ensuring that anything that has been deprecated or abandoned wasn’t being used.

Missing arkaine already

Recently I took on a contract job to fill the coffers a bit while HiredCoach handles its initial launch. Nothing that I can talk that much about publicly, but I can reveal that it’s your typical AI office assistant for a particular business process. As specific as it is exciting a description, I’m sure.

Given that I recently wrote an entire article about the highs and lows of my custom framework, arkaine - and within I mention that I lkely won’t continue developemnt on that particular implementation of those ideas I wouldn’t exactly want to pull it out for a client hoping for their PoC to be easily maintainable for future developers as they pursue it; it’s too esoteric a framework and oto tied to my own development preferences.

That being said, I still have difficulty finding a replacement that works in the way I enjoy or rate highly. I find myself wishing for several of the features and niceties I baked into arkaine. I view it as a reassuring sign that I was onto something with a few ideas there.

As an additional note - Web research agents that are useful are hard to get right. I’ve built these three times now and still feel like they are tricky to make them reliable and performant.

I started working on “arkaine 2.0” (which will likely be the 0.1.0); whether I continue on it remains to be seen, as it is architectually a gigantic change. I’m playing with Merkle trees and more controlled syncing paired with better serialization and compression, as well sa more flexible composable functions without falling into the overly verbose repetitive context nesting we ran into before.